Sebastian Raschka 发布 11 小时从零构建推理模型视频课程
Build Your Own Reasoning Model: A Full Video Course
Sebastian Raschka 发布 8 个从零构建推理模型的编程视频,共 11 小时,基于预训练 Qwen3 0.6B 用 Python 和 PyTorch 实现推理方法。
I have written a lot about reasoning models here over the last two years on Ahead of AI, including a recent article on mechanisms to control reasoning effort levels in contemporary LLMs. Reasoning models are still as relevant as ever. In fact, almost all current-generation LLMs today are reasoning models or offer a reasoning mode.
For those who are interested in how reasoning models work, including inference scaling, reinforcement learning, and distillation, I wrote my recent Build Reasoning Model (From Scratch), which implements these from the ground up in PyTorch, which, in my experience, is still the best way to understand and learn how things really work.
Now, in the last few months, I also sat down and recorded accompanying lectures I wanted to share with you. So, below, you will find eight reasoning model-from-scratch coding videos (11 hours of content).
We start with a pre-trained LLM and implement methods to evaluate and improve it in Python and PyTorch. So, if you enjoyed my Coding LLMs from the Ground Up course last year, this is essentially the sequel (but you can also watch it without the prior course as a prerequisite).
I’m currently taking a short break and will be back soon with more exciting LLM research roundups next month. In the meantime, I hope you enjoy coding along!
How LLMs, reasoning models, and agents relate and fit together
As a small side note, and since I often get asked how reasoning models relate to today’s AI agents, here’s a short section on this before getting started with the videos.
A reasoning model is essentially an upgrade from a conventional LLM, that is, adding more post-training via reinforcement learning with verifiable rewards (and optionally inference scaling techniques) to make it more capable of solving more challenging problems. Classically, reasoning models are developed for math and code, but the capabilities can generalize to other problem domains as well.
A reasoning model then functions as the engine inside an agent harness, where the agent harness is a software or tooling framework around the LLM/reasoning model to tackle even more challenging problems (bigger coding tasks, travel booking, and all other sorts of personal assistant tasks). The task of the harness is sophisticated context management and giving the LLM access to tools.
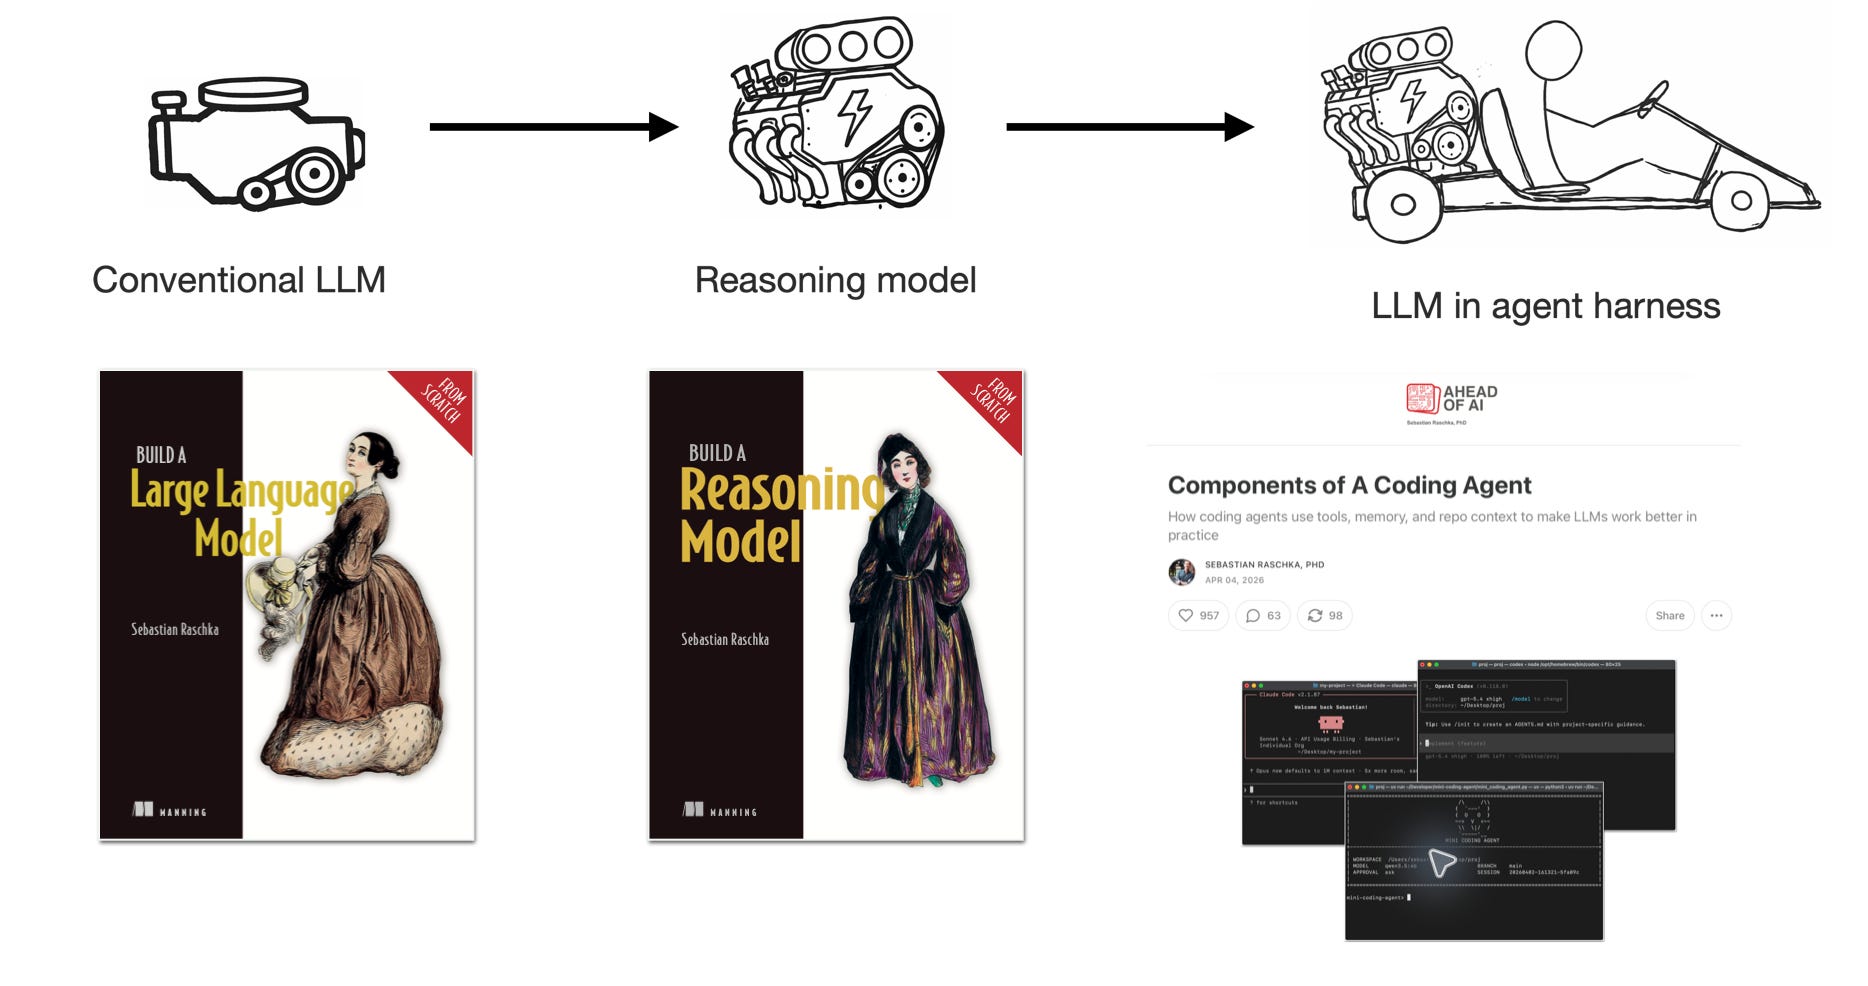
Figure 1: An engine analogy for conventional LLMs, reasoning models, and agent harnesses. Figure from my Components of a Coding Agent article.
In this analogy depicted in the figure above, the model is the engine, and the agent harness adds the machinery that lets us use it for various things (as an upgrade from a simple chatbot interface). An agent can use either a conventional LLM or a reasoning model, but reasoning models are the more typical choice as they are more capable. (As mentioned above, most current-gen LLMs are reasoning models with variable reasoning effort settings.)
So, the bottom line is that reasoning models, as the “engine,” remain an important part of understanding modern LLM agents.
The resources accompanying these topics shown above are:
The Build a Large Language Model (From Scratch) book and videos
The Build A Reasoning Model (From Scratch) book (and videos below)
The Components of a Coding Agent article on Substack
The videos below focus on developing the reasoning model that can power such a system.
Scope and prerequisites
The reasoning-from-scratch videos focus on a small pre-trained Qwen3 model, where we implement the reasoning methods ourselves in Python and PyTorch. Starting with a pre-trained model lets us focus on the interesting part: evaluation, inference-time scaling, reinforcement learning, and distillation.
Regarding the prerequisites, I recommend being comfortable with Python and PyTorch. I designed the reasoning materials as standalone content, so the previous Build A Large Language Model (From Scratch) content is recommended but not strictly required.
Compute-resource-wise, you can work through the early text-generation and evaluation examples on a CPU. For the later experiments, especially training, a GPU makes the work much more practical. The first video covers the setup and some more recommendations; the repository also includes hardware and environment recommendations.
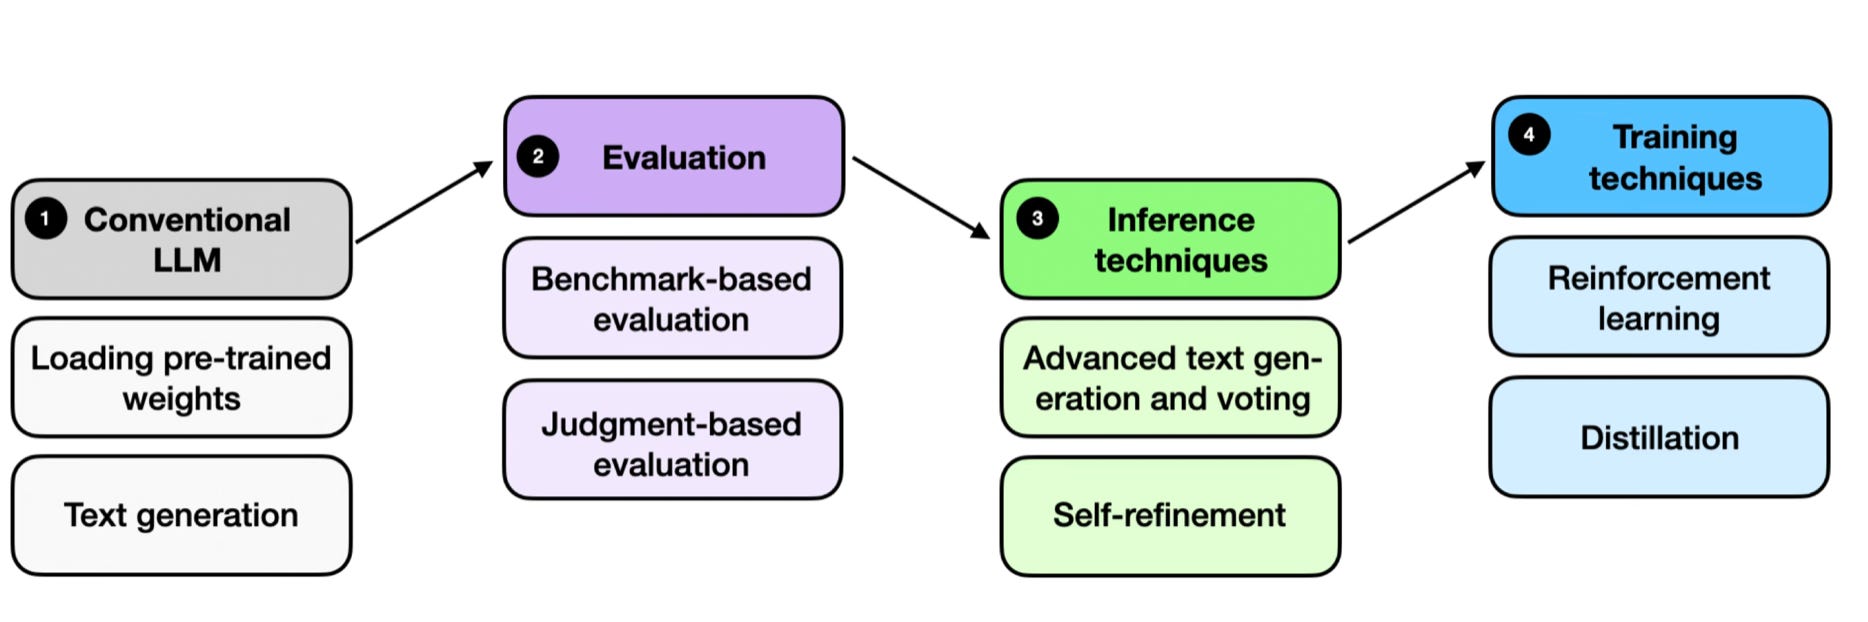
Figure 2: An overview of the topics being covered.
The companion book
These videos accompany my book, Build a Reasoning Model (From Scratch). If you like to read through the explanation in more detail and at your own pace, work through exercises, and so on, I recommend the book as a companion here.
For the most in-depth learning experience, my suggestion is to read a chapter, work through its code alongside the corresponding video, and then try the exercises.
The book is available from Manning and Amazon, and the print edition is in color!
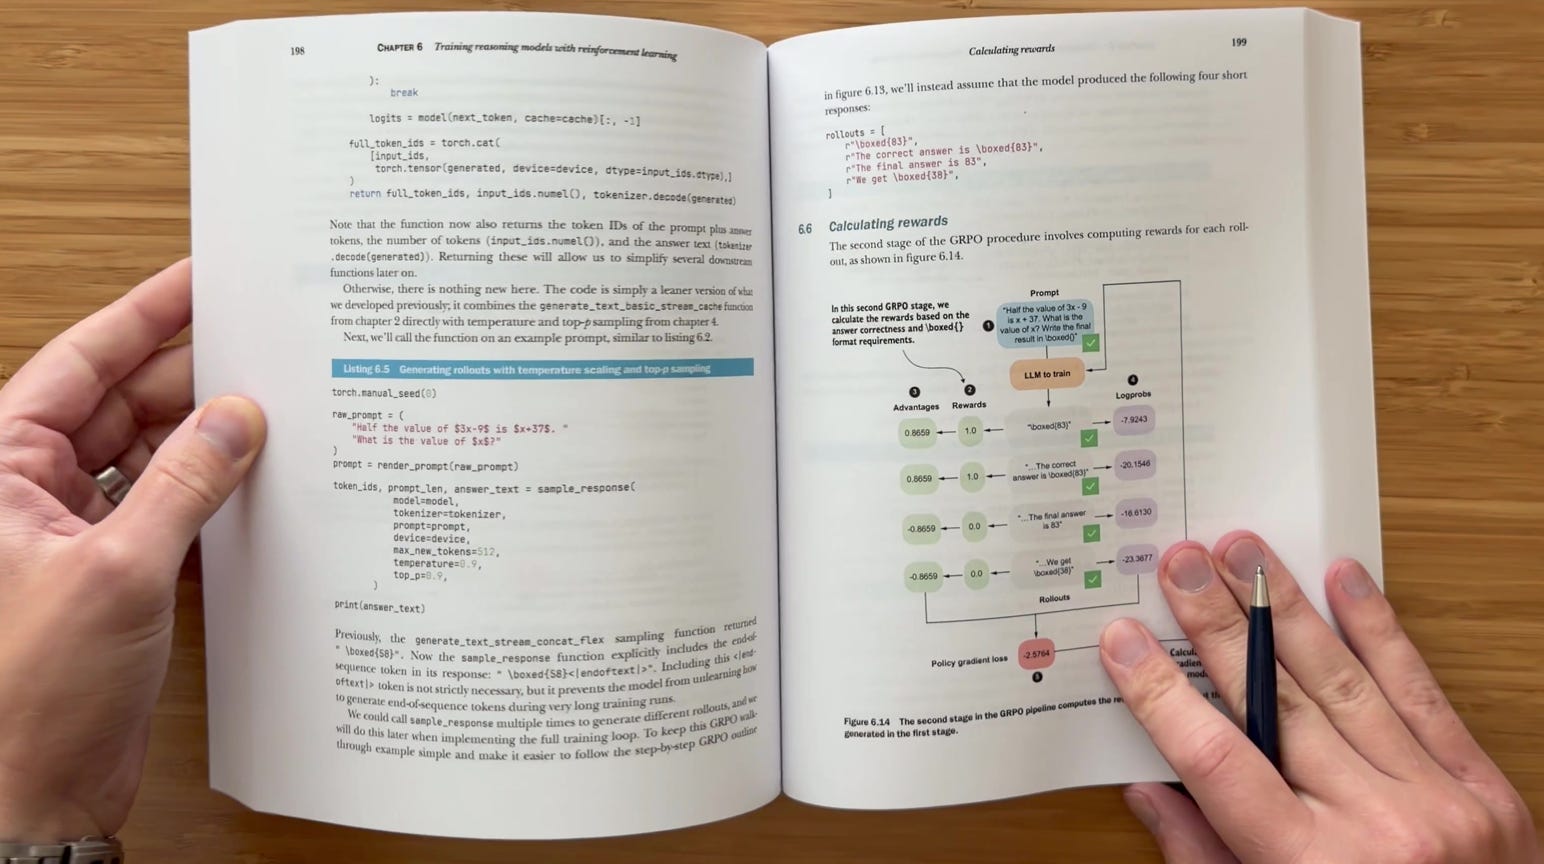
Figure 3: A random excerpt from the Build a Reasoning Model (From Scratch) print book.
Thank you to everyone who has picked up a copy or recommended it to a friend. Your support helps me keep creating these materials.
The videos
As a last, quick side note before getting to the main videos below: For a shorter, more conceptual overview, I also recommend my AI Reasoning Models course on LinkedIn Learning (it should be free for 24h when accessing it via the link there, which shouldn’t then require a LinkedIn Premium subscription).
The course is about 90 minutes and explains how reasoning models work, covering the main ideas behind inference-time scaling, reinforcement learning, and distillation. It’s a good optional preview if you’d like the main ideas without working through the full implementations below.
To get to the main part of this article, here are the eight main lecture videos.
1. Motivation and code setup
The first video starts with an explanation of the relationship between conventional LLMs, reasoning models, and agents. Next, the main topic of the video is setting up the coding environment. This includes installing the Python and PyTorch dependencies (with uv), among others. I also discuss hardware choices and common setup issues.
Topics covered
The relationship between conventional LLMs, reasoning models, and agent harnesses
On the benefits of learning through code implementations
The scope of this video series
Installing Python dependencies
Choosing hardware and checking CUDA or Apple Silicon support
Using a remote GPU with VS Code and troubleshooting the environment
Watch video 1 · Setup instructions
2. Loading a base model, text generation, and KV caching
Before adding reasoning methods in the upcoming videos, we need a working base model. Instead of training it from scratch, since that would be a whole other book (see Build A Large Language Model (From Scratch)), we start with a pre-trained model.
Here, we load the pre-trained weights of a Qwen3 0.6B model. Then, we implement the text-generation process via a streaming text generator and add KV caching and model compilation to make text generation more efficient.
These implementations give us the baseline and base components we will evaluate and improve in the following videos.
Topics covered
Encoding text as tokens and decoding it back into text
Downloading Qwen3 weights and loading the model on the selected compute device
Going over tensor shapes, logits, and next-token predictions
Implementing greedy decoding and streaming text generation
Handling end-of-sequence tokens and measuring generation speed
Adding a KV cache to reuse attention keys and values
Combining KV caching with
torch.compileand comparing hardware performance
Watch video 2 · Chapter 2 code
3. Building a verifier for evaluation and reinforcement learning
In this lecture, we build a math-answer verifier step by step, from answer extraction to normalization and checking mathematical equivalence. We then use it to evaluate the model on MATH-500.
We use this verifier to evaluate the base model’s performance on the MATH-500 evaluation dataset.
However, the verifier also has a second job later in the series: providing the reward signal for reinforcement learning with verifiable rewards (RLVR).
Topics covered
Intro to verifiers and how they fit into LLM evaluation methods (other methods are covered in the book’s appendix)
Reusing answer verification as a reward signal for RLVR (more on that in chapter 6)
The verifier flow, including extracting final answers, normalizing answers and checking mathematical equivalence
Building an answer grader and an evaluation loop for MATH-500
Comparing base and reasoning models on MATH-500
Watch video 3 · Chapter 3 code
4. Inference-time scaling: sampling and self-consistency
Now we explore ways to improve answers while keeping the model weights fixed. But before implementing specific inference-scaling techniques, we first implement methods to generate diverse answers from the same prompt (this is standard practice in proprietary LLM chatbots, such as ChatGPT).
Concretely, we implement temperature scaling, multinomial sampling, and top-p filtering to generate diverse responses. Then we combine multiple responses through self-consistency, using majority voting over their final answers.
We also examine the tradeoff between answer accuracy and the extra computation needed to generate more candidates.
Topics covered
Comparing how additional compute benefits model performance during training and during inference
A gentle intro to inference-scaling through chain-of-thought prompts
Implementing temperature scaling and multinomial sampling to generate diverse answers
Adding top-p filtering to control the quality of the diverse answers
Combining candidate answers through self-consistency, one of the most popular inference scaling techniques
Evaluating MATH-500 accuracy against the cost of additional inference compute
Watch video 4 · Chapter 4 code
5. Inference-time scaling: scoring and self-refinement
Building on the previous video, we implement scoring functions to compare multiple answers generated from the same prompt. We can also use these scoring methods to break ties in self-consistency (covered in the previous lecture).
The scoring methods covered here include computing token and sequence log probabilities (this will also be relevant in the later reinforcement learning chapters). We then implement a self-refinement loop in which the model critiques an answer and attempts a revision.
The evaluation lets us check how useful those additional steps are for our model.
Topics covered
Using scoring functions for comparing multiple answers and breaking ties
Implementing a simple heuristic scorer
Computing token probabilities and sequence likelihoods (also relevant for the following lectures)
Using log probabilities for improved numerical stability
Building a self-refinement loop for generating critiques and revised answers
Evaluating self-refinement on MATH-500
Watch video 5 · Chapter 5 code
6. Reinforcement learning: implementing GRPO for RLVR
In this lecture, we move on to implementing a training technique called Reinforcement Learning with Verifiable Rewards (RLVR). We first implement a simplified version of Group Relative Policy Optimization (GRPO), generate groups of responses, score them with our verifier, and use their relative rewards for the model weight updates during training.
Topics covered
Generating reasoning traces and understanding the relationship between answer lengths and problem-solving abilities
Discussion and comparison of two important LLM post-training methods: Reinforcement Learning with Human Feedback (RLHF) and Reinforcement Learning with Verifiable Rewards (RLVR)
Turning verifier scores into rewards and relative advantages
Computing sequence log probabilities and a simplified GRPO loss
Assembling the training loop with logging and checkpoint saves
Evaluating checkpoints and checking training stability and memory needs
Watch video 6 · Chapter 6 code
7. Reinforcement learning: tracking, clipped policy ratios, and KL terms
Now that we implemented the training loop in the previous lecture, we can revisit it and analyze the training runs in more detail.
Concretely, this video adds more training metrics for inspection and analysis, including entropy and advantage statistics, clipped policy ratios, KL loss term values, and formatted rewards.
We then review the training logs and evaluation results to understand what these additions do and whether additions such as clipped policy ratios and KL loss terms are helpful.
Topics covered
Running longer training experiments and interpreting their logs
Tracking advantages and entropy to understand training behavior
Implementing clipping in the policy loss and analyzing its effects
Adding a KL loss term and discussing reward hacking
Understanding limitations of the simplified KL formulation
Implementing format rewards and conditioning them on answer correctness
Comparing checkpoints on MATH-500 and exploring further GRPO research
Watch video 7 · Chapter 7 code
8. Distilling a reasoning model
Finally, we explore another way to train a small reasoning model, that is, learning from answers generated by a stronger (and bigger) teacher model. We discuss different forms of distillation, prepare reasoning data, and implement the supervised training loop.
We finish this lecture and course by evaluating the distilled model on MATH-500 and comparing the results. This rounds out the series with an alternative to developing reasoning capabilities through reinforcement learning.
Topics covered
Comparing the different combination and approaches to distillation, including soft and hard distillation, and on-policy and off-policy distillation
Creating and collecting teacher-generated answers for the MATH dataset (using DeepSeek R1)
Preparing the distillation dataset, including tokenization and training/validation/test splits
Computing answer-token log probabilities and understanding the cross-entropy loss
Implementing supervised training and tracking training and validation losses
Evaluating checkpoints on MATH-500 and comparing distillation results
Watch video 8 · Chapter 8 code
Final words
As you watch these lectures, I encourage you to pause occasionally and try a small experiment of your own if something interesting comes to mind.
For example, feel free to change the sampling settings, inspect a few failed answers, or try variations of different ideas similar to the suggestions in the exercises.
And if you would like the full written walkthrough, figures, and exercises alongside the videos, you can find Build a Reasoning Model (From Scratch) at Manning and Amazon.
Thanks for reading and supporting Ahead of AI. I am taking a short break to regenerate, and I look forward to being back with the next round of LLM research articles next month.
In the meantime, happy viewing and tinkering!
来源:Ahead of AI · magazine.sebastianraschka.com