LlamaIndex 0.9.15 全面支持 Gemini 与 Semantic Retriever API
LlamaIndex + Gemini
LlamaIndex 在 Gemini 公开发布当天宣布成为 day 1 合作伙伴,自 0.9.15 起全面支持 Gemini Pro、Gemini Ultra 及多模态 gemini-pro-vision,覆盖流式、异步、补全与聊天共 8 种组合。
LlamaIndex 作为 Gemini 首发合作方,给出了完整接入方式与三种高级 RAG 组合用法,读者可直接照做。
(由 Jerry Liu、Haotian Zhang、Logan Markewich 和 Laurie Voss @ LlamaIndex 共同撰写)
今天是 Google 公开发布其最新 AI 模型 Gemini 的日子。我们很荣幸成为 Gemini 的首日发布合作伙伴,LlamaIndex 今天即可提供支持!
立即探索我们的免费和付费方案。
从 0.9.15 版本开始,LlamaIndex 全面支持所有当前已发布和即将推出的 Gemini 模型(Gemini Pro、Gemini Ultra)。我们既支持“纯文本”Gemini 变体(文本输入/文本输出格式),也支持多模态变体(同时接受文本和图像作为输入,并输出文本)。我们进行了一些基础性的多模态抽象变更,以支持 Gemini 多模态接口,该接口允许用户输入多张图像以及文本。我们的 Gemini 集成也是功能完备的:它们支持(非流式、流式)、(同步、异步)以及(文本补全、聊天消息)格式——总共 8 种组合。
此外,我们还支持全新的语义检索器 API,它将存储、嵌入模型、检索和 LLM 打包在一个 RAG 流水线中。我们向你展示如何单独使用它,或者将其与 LlamaIndex 组件分解并打包,以创建高级 RAG 流水线。
非常感谢 Google Labs 和语义检索器团队帮助我们获得早期访问权限。
- Google Labs:Mark McDonald、Josh Gordon、Arthur Soroken
- 语义检索器:Lawrence Tsang、Cher Hu
以下部分详细介绍了我们在 LlamaIndex 中全新的 Gemini 和语义检索器抽象。如果你现在不想阅读,请务必收藏我们下面的详细 notebook 指南!
Gemini 发布与支持
关于 Gemini 的报道铺天盖地,它在各种基准测试中都号称有令人印象深刻的表现。Ultra 版本(尚未公开可用)在从 MMLU 到 Big-Bench Hard 再到数学和编码任务的基准测试中都优于 GPT-4。它们的多模态演示展示了从科学论文理解到文献综述等领域的图像/文本联合理解能力。
让我们通过示例来了解如何在 LlamaIndex 中使用 Gemini。我们将介绍文本模型(from llama_index.llms import Gemini)以及多模态模型(from llama_index.multi_modal_llms.gemini import GeminiMultiModal)
文本模型
我们从文本模型开始。在下面的代码片段中,我们展示了从补全到聊天再到流式再到异步的各种不同配置。
from llama_index.llms import Gemini

# completion
resp = Gemini().complete("Write a poem about a magic backpack")
# chat
messages = [
    ChatMessage(role="user", content="Hello friend!"),
    ChatMessage(role="assistant", content="Yarr what is shakin' matey?"),
    ChatMessage(
        role="user", content="Help me decide what to have for dinner."
    ),
]
resp = Gemini().chat(messages)
# streaming (completion)
llm = Gemini()
resp = llm.stream_complete(
    "The story of Sourcrust, the bread creature, is really interesting. It all started when..."
)
# streaming (chat)
llm = Gemini()
messages = [
    ChatMessage(role="user", content="Hello friend!"),
    ChatMessage(role="assistant", content="Yarr what is shakin' matey?"),
    ChatMessage(
        role="user", content="Help me decide what to have for dinner."
    ),
]
resp = llm.stream_chat(messages)
# async completion
resp = await llm.acomplete("Llamas are famous for ")
print(resp)
# async streaming (completion)
resp = await llm.astream_complete("Llamas are famous for ")
async for chunk in resp:
    print(chunk.text, end="")
Gemini 类当然有可以设置的参数。这包括 model_name、temperature、max_tokens 和 generate_kwargs。
例如,你可以这样做:
llm = Gemini(model="models/gemini-ultra")多模态模型
在这个 notebook 中,我们测试了具有多模态输入功能的 gemini-pro-vision 变体。它包含以下特性:
- 同时支持
complete和chat能力 - 支持流式和异步
- 支持在补全端点中除了文本之外还输入多张图像
- 未来工作:在我们的抽象中支持文本和图像交错的多轮聊天,但尚未为 gemini-pro-vision 启用。
让我们来看一个具体示例。假设我们得到了一张以下场景的图片:
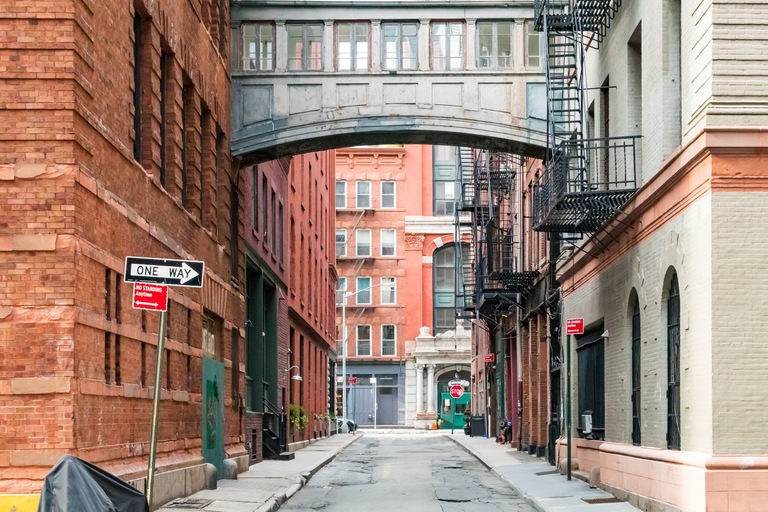

然后我们可以初始化 Gemini Vision 模型,并向它提问:“识别这张照片拍摄的城市”:
from llama_index.multi_modal_llms.gemini import GeminiMultiModal
from llama_index.multi_modal_llms.generic_utils import (
    load_image_urls,
)

image_urls = [
    "<https://storage.googleapis.com/generativeai-downloads/data/scene.jpg>",
    # Add yours here!
]
image_documents = load_image_urls(image_urls)
gemini_pro = GeminiMultiModal(model="models/gemini-pro")
complete_response = gemini_pro.complete(
    prompt="Identify the city where this photo was taken.",
    image_documents=image_documents,
)
我们的回答如下:
New York City我们也可以插入多张图片。这里有一个包含梅西和罗马斗兽场图片的示例。
image_urls = [
    "<https://www.sportsnet.ca/wp-content/uploads/2023/11/CP1688996471-1040x572.jpg>",
    "<https://res.cloudinary.com/hello-tickets/image/upload/c_limit,f_auto,q_auto,w_1920/v1640835927/o3pfl41q7m5bj8jardk0.jpg>",
]
image_documents_1 = load_image_urls(image_urls)
response_multi = gemini_pro.complete(
    prompt="is there any relationship between those images?",
    image_documents=image_documents_1,
)
print(response_multi)
多模态用例(结构化输出、RAG)
我们创建了关于不同多模态用例的大量资源,从结构化输出提取到 RAG。
感谢 Haotian Zhang,我们为 Gemini 的两种用例都提供了示例。请查看我们详尽的 notebook 指南以了解更多细节。同时,这里是最终结果!
使用 Gemini Pro Vision 进行结构化数据提取

输出:
('restaurant', 'La Mar by Gaston Acurio')
('food', 'South American')
('location', '500 Brickell Key Dr, Miami, FL 33131')
('category', 'Restaurant')
('hours', 'Open ⋅ Closes 11 PM')
('price', 4.0)
('rating', 4)
('review', '4.4 (2,104)')
('description', 'Chic waterfront find offering Peruvian & fusion fare, plus bars for cocktails, ceviche & anticucho.')
('nearby_tourist_places', 'Brickell Key Park')
多模态 RAG
我们在多张餐厅图片上运行结构化输出提取器,索引这些节点,然后提问“为我推荐一家奥兰多餐厅及其附近的旅游景点”
I recommend Mythos Restaurant in Orlando. It is an American restaurant located at 6000 Universal Blvd, Orlando, FL 32819, United States. It has a rating of 4 and a review score of 4.3 based on 2,115 reviews. The restaurant offers a mythic underwater-themed dining experience with a view of Universal Studios' Inland Sea. It is located near popular tourist places such as Universal's Islands of Adventure, Skull Island: Reign of Kong, The Wizarding World of Harry Potter, Jurassic Park River Adventure, Hollywood Rip Ride Rockit, and Universal Studios Florida.语义检索器
生成式语言语义检索器提供专门的嵌入模型以实现高质量检索,以及一个经过调优的 LLM,用于在安全设置下生成有依据的输出。
它可以开箱即用(使用我们的GoogleIndex),也可以分解为不同的组件(GoogleVectorStore 和 GoogleTextSynthesizer)并与 LlamaIndex 抽象结合使用!
我们完整的语义检索器 notebook 指南在此。
开箱即用配置
只需几行设置即可开箱即用。只需定义索引、插入节点,然后获取查询引擎:
from llama_index.indices.managed.google.generativeai import GoogleIndex

index = GoogleIndex.from_corpus(corpus_id="<corpus_id>")
index.insert_documents(nodes)
query_engine = index.as_query_engine(...)
response = query_engine.query("<query>")
这里一个很酷的功能是,Google 的查询引擎支持不同的回答风格以及安全设置。
回答风格:
- ABSTRACTIVE(简洁但抽象)
- EXTRACTIVE(简短且提取式)
- VERBOSE(额外细节)
安全设置
你可以在查询引擎中指定安全设置,这让你可以定义在不同设置下回答是否明确的护栏。更多信息请参阅generative-ai-python库。
分解为不同组件
GoogleIndex 建立在两个组件之上:向量存储(GoogleVectorStore)和响应合成器(GoogleTextSynthesizer)。你可以将这些作为模块化组件与 LlamaIndex 抽象结合使用,以创建高级 RAG。
该 notebook 指南重点介绍了三个高级 RAG 用例:
- Google Retriever + 重排序:使用语义检索器返回相关结果,然后使用我们的重排序模块在将结果送入响应合成之前进行处理/过滤。
- 多查询 + Google Retriever:使用我们的多查询能力,例如我们的
MultiStepQueryEngine,将复杂问题分解为多个步骤,并针对语义检索器执行每个步骤。 - HyDE + Google Retriever:HyDE 是一种流行的查询转换技术,它根据查询幻觉出一个答案,并使用幻觉出的答案进行嵌入查找。将其用作语义检索器检索步骤之前的一步。
结论
这里内容非常丰富,即便如此,这篇博客文章甚至没有涵盖我们今天发布内容的一半。
请务必查看我们详尽的 notebook 指南!下面再次链接这些资源:
再次特别感谢 Google 团队以及 LlamaIndex 团队的 Haotian Zhang 和 Logan Markewich,为本次发布所做的一切准备工作。
来源:LlamaIndex:产品、工程与评测 · llamaindex.ai